· Goher K · AI & Tech · 20 min read
Natural Language Processing in Modern Enterprise AI Tech for 2027
Explore how Natural Language Processing (NLP) powers modern AI architectures, transformers, large language models, and enterprise conversational automation.
The Foundation of Modern Communication: NLP’s Pervasive Influence
Natural Language Processing (NLP) stands as a pivotal discipline at the intersection of computer science, artificial intelligence, and computational linguistics. Its core objective is to enable computers to understand, interpret, and generate human language in a valuable way. In an increasingly data-driven world, where the vast majority of information is unstructured text, NLP provides the tools and techniques necessary to unlock insights, automate tasks, and create more intuitive human-computer interfaces. From the humble beginnings of rule-based systems to the sophisticated deep learning architectures of today, NLP has continuously evolved, fundamentally transforming how we interact with technology and each other. Its impact is no longer confined to academic research; it is deeply embedded in the products and services that define modern life, driving innovation across various sectors and setting new benchmarks for intelligent systems.
From Symbolic AI to Statistical Models
Early NLP efforts, predominantly in the 1950s and 1960s, relied heavily on symbolic AI approaches. These methods involved crafting intricate sets of rules, grammars, and dictionaries to parse and generate language. Think of systems meticulously designed to understand sentence structures based on predefined grammatical rules, or chatbots that could respond to a limited set of keywords with pre-programmed answers. While these systems offered initial glimpses into the potential of language processing, their inherent rigidity proved to be a significant limitation. Human language is incredibly nuanced, ambiguous, and dynamic; hard-coding every possible linguistic variation quickly became an insurmountable task. The fragility of these rule-based systems meant they struggled with even minor deviations from their programmed knowledge, leading to a high rate of failure in real-world applications.
The late 1980s and early 1990s marked a significant shift towards statistical NLP. This paradigm leveraged large corpora of text data to learn patterns and relationships in language probabilistically. Instead of explicit rules, algorithms would infer the likelihood of certain word sequences or grammatical structures occurring. Techniques like n-grams, Hidden Markov Models (HMMs), and Conditional Random Fields (CRFs) became prominent. These statistical models were more robust to linguistic variation and ambiguity, as they could generalize from observed data. The ability to “learn” from data rather than being explicitly programmed was a game-changer, paving the way for more sophisticated applications like spam filtering, part-of-speech tagging, and early forms of machine translation. This era laid the groundwork for the data-intensive approaches that would dominate NLP in the following decades.
The Deep Learning Revolution
The turn of the 21st century and, more profoundly, the 2010s witnessed the ascendance of deep learning in NLP. Inspired by the structure and function of the human brain, deep neural networks offered unprecedented capabilities in pattern recognition and representation learning. Initially, recurrent neural networks (RNNs) and their variants, such as Long Short-Term Memory (LSTM) networks and Gated Recurrent Units (GRUs), excelled at processing sequential data like text. These architectures could capture long-range dependencies in sentences, addressing a key limitation of earlier statistical models. This led to significant breakthroughs in tasks like machine translation, sentiment analysis, and question answering.
However, the true inflection point arrived with modern Transformer architecture advancements heading into 2027. Transformers, with their attention mechanisms, revolutionized NLP by allowing models to process all parts of a sequence in parallel, significantly improving training efficiency and scalability. This innovation enabled the development of exceptionally large language models (LLMs) like GPT (Generative Pre-trained Transformer) series, BERT (Bidirectional Encoder Representations from Transformers), and more recently, Gemma and Mistral. These models are pre-trained on vast amounts of internet text, learning intricate linguistic patterns, semantic relationships, and even a degree of world knowledge. The “pre-training then fine-tuning” paradigm has become standard, where a large general-purpose model is adapted to specific downstream tasks with smaller, task-specific datasets. This deep learning revolution has not only pushed the boundaries of what’s possible in NLP but has also democratized access to highly powerful language understanding and generation capabilities. The ability of LLMs to generate coherent, contextually relevant, and even creative text has opened up entirely new avenues for innovation.
Core NLP Techniques and Their Applications
The breadth of NLP techniques is vast, ranging from foundational linguistic analysis to advanced semantic understanding and generation. Each technique addresses specific challenges in enabling computers to process and interact with human language, contributing to the overall intelligence of modern AI systems.
Text Preprocessing and Feature Extraction
Before any advanced NLP model can operate effectively, raw text data typically undergoes a series of preprocessing steps. This crucial phase transforms unstructured text into a format that is amenable to computational analysis. Tokenization, the process of breaking down text into smaller units (words, subwords, or characters), is often the first step. For instance, “Don’t” might be tokenized into “Do” and “n’t”. Stemming and lemmatization aim to reduce words to their base or root form, e.g., “running,” “runs,” and “ran” might all be reduced to “run.” This helps in normalizing text and reducing vocabulary size, which can improve model performance. Stop-word removal (eliminating common words like “the,” “a,” “is” that often carry little semantic meaning) is another common step, although its utility can vary depending on the specific NLP task.
Feature extraction is about converting textual data into numerical representations that machine learning models can understand. Traditional methods include Bag-of-Words (BoW) and TF-IDF (Term Frequency-Inverse Document Frequency), which represent documents as vectors where each dimension corresponds to a word and its frequency or importance. While simple, these methods lose word order and context. Word embeddings, such as Word2Vec and GloVe, revolutionized feature extraction by representing words as dense vectors in a continuous vector space, where semantically similar words are located closer together. More advanced context-aware embeddings, like those generated by BERT or GPT-series models, capture the meaning of a word based on its surrounding context within a sentence, offering a much richer and nuanced representation. These embeddings are fundamental to the success of modern deep learning NLP models.
Natural Language Understanding (NLU)
NLU is a subset of NLP focused on enabling computers to comprehend the meaning of human language. This involves a spectrum of tasks that move beyond simple word matching to deep semantic interpretation. Named Entity Recognition (NER), for instance, identifies and classifies named entities in text into predefined categories such as person, organization, location, medical code, or date. This is vital for information extraction from unstructured text. Part-of-Speech (POS) tagging assigns grammatical labels (noun, verb, adjective, etc.) to words, which is crucial for syntactic parsing.
Sentiment analysis, or opinion mining, determines the emotional tone behind a piece of text—whether it’s positive, negative, or neutral. This has widespread applications in customer feedback analysis, brand monitoring, and social media analytics. Text classification, a broader NLU task, involves assigning predefined categories to entire documents or pieces of text. Examples include spam detection, topic categorization, and intent recognition in chatbots. More advanced NLU tasks involve question answering (QA) systems that can understand a question posed in natural language and retrieve or generate a precise answer from a body of text. The ability of modern LLMs to effectively perform these NLU tasks, often with zero-shot or few-shot learning, demonstrates the significant advancements in this area.
Natural Language Generation (NLG)
NLG is the process of generating human-like text from structured data or an internal representation. While NLU focuses on understanding, NLG focuses on expressing. Early NLG systems were largely template-based, filling pre-defined slots with data. Modern NLG, heavily influenced by deep learning, is far more sophisticated. Conditional text generation, where models generate text based on a given prompt or context, is now commonplace. This includes tasks like summarization, which condenses longer texts into shorter, coherent versions while retaining key information. Abstractive summarization, specifically, paraphrases and generates new sentences rather than just extracting existing ones.
Machine translation, another prominent NLG application, translates text from one natural language to another while preserving meaning and nuance. Recent advancements, exemplified by models like Google TranslateGemma, have significantly improved the fluency and accuracy of machine translation across 55 languages, making global communication more seamless. Conversational AI, encompassing chatbots and virtual assistants, heavily relies on NLG to generate natural and appropriate responses to user queries. Furthermore, NLG is being used for creative writing, content generation (e.g., news articles, marketing copy), and even code generation. The sophistication of current NLG models allows for the creation of text that is often indistinguishable from human-written content, presenting both immense opportunities and ethical considerations.
NLP’s Impact on Industry and Society
The pervasive influence of NLP has fundamentally reshaped numerous industries and aspects of daily life, driving efficiency, enhancing user experiences, and opening up new frontiers for innovation.
Enhancing Customer Experience
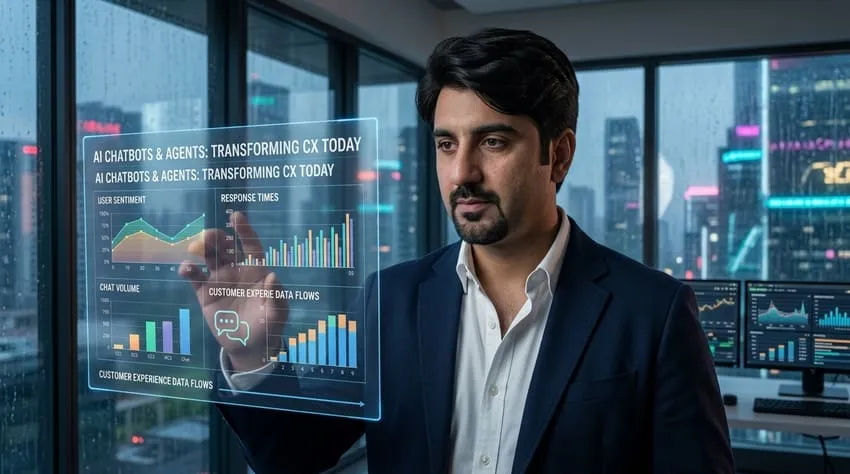
One of the most visible applications of NLP is in customer service. Chatbots and virtual assistants, powered by advanced NLP, handle a significant volume of customer inquiries, providing instant support, answering FAQs, and guiding users through processes. This automation reduces response times, lowers operational costs, and frees human agents to focus on more complex issues. Beyond basic Q&A, sentiment analysis of customer feedback allows businesses to gauge satisfaction levels, identify pain points, and proactively address negative experiences. Companies can analyze social media mentions, customer reviews, and support tickets to understand public perception and tailor their strategies. Furthermore, personalized recommendations, driven by NLP understanding of user preferences and historical interactions, enhance the shopping experience across e-commerce platforms, streaming services, and content providers. The ability to quickly understand customer intent and provide relevant, timely information is a cornerstone of modern customer engagement strategies.
Revolutionizing Healthcare and Life Sciences
In healthcare, NLP is proving to be a transformative force. One critical application is the analysis of Electronic Health Records (EHRs). These records often contain a wealth of unstructured text, from physician’s notes to discharge summaries. NLP extracts crucial information—diagnoses, symptoms, medications, procedures, and patient history—allowing for better data aggregation, research, and clinical decision support. The MIT report on a new language-processing tool for identifying individuals at highest suicide risk from text exemplifies NLP’s potential in mental health intervention, enabling faster and more targeted support. Beyond diagnostics, NLP assists in drug discovery by analyzing vast scientific literature to identify potential drug targets, adverse effects, and research gaps. It also streamlines the administrative burden in healthcare by automating tasks like medical coding and claim processing. The ability to derive actionable insights from complex medical text accelerates research, improves patient outcomes, and enhances the efficiency of healthcare systems.
Powering Information Retrieval and Knowledge Management
The explosion of digital information necessitates sophisticated tools for finding, organizing, and synthesizing knowledge. NLP is at the heart of modern search engines, allowing them to understand natural language queries rather than just keyword matching, thereby providing more relevant results. Enterprise search solutions leverage NLP to index internal documents, emails, and knowledge bases, making it easier for employees to find critical information quickly. Text summarization tools, a key NLG application, help in digesting long reports, research papers, and news articles, providing concise overviews that save time and aid in decision-making. Information extraction techniques automatically pull structured data from unstructured text, populating databases and knowledge graphs, which in turn enhances data governance and accessibility. The ability to intelligently manage and retrieve information is paramount for businesses and research institutions navigating the “big data” landscape.
Enabling Global Communication and Collaboration
Machine translation has broken down language barriers, fostering global communication and collaboration. From personal travel apps to large-scale enterprise solutions, NLP-powered translation services enable real-time communication across different languages. Google TranslateGemma, with its open models supporting 55 languages on various devices, highlights the continuous push for more accurate and accessible translation. Beyond direct translation, NLP aids in cross-lingual information retrieval, allowing users to search for content in one language and retrieve relevant documents in another. The development of advanced speech-to-text and voice models, as noted by DeepLearning.AI and exemplified by Mistral Voxtral, further bridges communication gaps by converting spoken language into text and vice versa, facilitating international meetings, content localization, and accessibility for diverse user groups. Full-duplex voice systems, capable of simultaneously speaking and listening, are bringing human-like conversational fluency to AI agents, further enhancing natural interaction across linguistic divides.
Discover the future of customer service with our innovative AI Chatbots & AI Agents. These intelligent systems are designed to enhance user interaction and streamline operations. Experience seamless communication and efficiency with our cutting-edge technology.
Emerging Trends and Future Directions
The field of NLP is dynamic, with continuous breakthroughs driven by research and the ever-growing demand for more sophisticated language AI. Several key trends are shaping its future, pushing the boundaries of what’s possible.
Large Language Models (LLMs) and Their Scaling Laws
The dominance of LLMs continues to grow, with models like GPT-4, Llama, and Mistral setting new performance benchmarks across a wide array of NLP tasks. These models, characterized by billions or even trillions of parameters, exhibit emergent capabilities such as complex reasoning, multi-task learning, and even a degree of creativity. A critical area of research, highlighted by Stanford HAI, involves understanding and leveraging scaling laws—empirical relationships between model performance, model size, dataset size, and computational resources. This research aims to optimize the training of these massive models, potentially reducing the exorbitant computational costs associated with them, thereby making advanced AI more accessible. The trend is not just about making models bigger but also smarter and more efficient in their learning.
Multimodality and Embodied AI
While traditional NLP focuses solely on text, the future increasingly lies in multimodality—integrating language with other data modalities such as images, video, and audio. Models that can understand and generate descriptions for images, caption videos, or respond to spoken commands by performing actions are becoming more prevalent. This convergence is leading to more holistic AI systems that perceive and interact with the world in a more human-like way. In embodied AI, LLMs are being used to help robots understand vague instructions by filtering irrelevant details before acting, as reported by MIT. This allows robots to interpret high-level commands, break them down into actionable steps, and execute them in physical environments, bridging the gap between abstract language and concrete actions. The ability of AI to not only understand language but also to perceive and act in the physical world represents a significant leap towards general artificial intelligence.
Explainable AI (XAI) and Trustworthy NLP
As NLP models become more complex and their decisions impact critical areas like healthcare and finance, the need for Explainable AI (XAI) becomes paramount. Users and developers need to understand why an AI model made a particular decision or generated a specific response. Research in XAI for NLP focuses on developing methods to visualize attention mechanisms, identify influential input tokens, and generate human-readable explanations for model outputs. This is crucial for building trust, ensuring fairness, and enabling debugging and auditing of AI systems. Alongside XAI, research into trustworthy NLP addresses issues like bias detection and mitigation in language models (which can inadvertently learn and perpetuate societal biases from their training data), robustness to adversarial attacks, and ensuring the factual accuracy of generated content. The continuous work by Google Research and IBM Research on factuality and reasoning in language models underscores this critical area of development, ensuring that the increasing power of NLP is wielded responsibly and ethically.
Advanced Conversational AI and Tool Use
The evolution of conversational AI continues with a focus on more natural, persistent, and context-aware interactions. Full-duplex voice systems, capable of speaking and listening simultaneously, are bringing human-like conversational fluency to AI agents, as noted by DeepLearning.AI. This allows for more seamless and less “turn-taking” interactions. A major area of advancement is “tool use” in LLMs, where models learn to interact with external tools and APIs (e.g., search engines, calculators, databases, code interpreters) to augment their capabilities. Instead of directly answering every query, an LLM might decide to “use a search engine” for up-to-date information or “run a calculation” for a precise numerical answer. This significantly extends the reasoning and problem-solving abilities of LLMs, enabling them to tackle tasks beyond their intrinsic knowledge and generation capabilities. The MIT research on AI agents asking better questions by using Battleship as a test bed, with small models outperforming larger ones at a fraction of the cost, highlights the ongoing innovation in making these agents more intelligent and resource-efficient in their decision-making and interaction with external environments.
Ethical Considerations and Challenges in NLP
xml encoding=“UTF-8”
| Metric | Description | Typical Range | Application |
|---|---|---|---|
| BLEU Score | Measures the quality of machine-translated text compared to human reference translations | 0 to 1 (higher is better) | Machine Translation |
| ROUGE Score | Evaluates the quality of summaries by comparing overlap with reference summaries | 0 to 1 (higher is better) | Text Summarization |
| Perplexity | Measures how well a probability model predicts a sample; lower perplexity indicates better performance | Typically > 1 (lower is better) | Language Modeling |
| F1 Score | Harmonic mean of precision and recall, used for classification tasks | 0 to 1 (higher is better) | Named Entity Recognition, Text Classification |
| Accuracy | Proportion of correctly predicted instances over total instances | 0 to 1 (higher is better) | Text Classification, Sentiment Analysis |
| Word Error Rate (WER) | Measures the number of errors in speech recognition output compared to reference transcript | 0 to 1 (lower is better) | Speech Recognition |
| Embedding Dimension | Number of features in word or sentence embeddings | 50 to 1024+ | Word Embeddings, Sentence Embeddings |
| Training Data Size | Amount of text data used to train NLP models | Thousands to billions of tokens | All NLP Tasks |
The rapid advancement of NLP brings with it a complex set of ethical considerations and challenges that must be addressed to ensure responsible and beneficial deployment of these powerful technologies.
Bias, Fairness, and Inclusivity
NLP models are trained on vast datasets of human-generated text, which often reflect and embed societal biases. If the training data contains stereotypes, discriminatory language, or underrepresentation of certain groups, the models will inevitably learn and perpetuate these biases. This can manifest in various ways: gender-biased word embeddings, racial bias in sentiment analysis, or unfair outcomes in applications like resume screening or loan applications. Addressing bias requires multi-faceted approaches, including careful dataset curation, algorithmic debiasing techniques, and continuous monitoring of model outputs for fairness. Ensuring inclusivity means designing NLP systems that work effectively for diverse linguistic backgrounds, accents, and dialects, and not just the dominant forms of language present in typical training datasets. This is a continuous effort requiring significant research and proactive development practices.
Misinformation, Disinformation, and Deepfakes
The ability of modern NLG models to generate highly coherent and convincing text presents a significant challenge in the fight against misinformation and disinformation. AI-generated text can be used to create fake news articles, social media posts, and persuasive propaganda at scale, making it difficult for humans to distinguish between authentic and fabricated content. The emergence of “deepfakes” (AI-generated synthetic media) extends this concern beyond text to audio and video. While NLP can also be a tool to detect and combat misinformation, the arms race between generative AI and detection methods is ongoing. Developing robust AI systems that can reliably identify and flag AI-generated content, especially persuasive and harmful content, is a critical area of research and policy development.
Privacy and Data Security
NLP models often require access to large amounts of text data, which can include sensitive personal information. The collection, storage, and processing of this data raise significant privacy concerns. Ensuring compliance with data protection regulations (like GDPR and CCPA) is paramount. Techniques like differential privacy and federated learning are being explored to train NLP models without directly exposing raw user data, allowing for privacy-preserving AI development. Furthermore, the security of LLM APIs and the data submitted to them is crucial. Developers must implement robust security measures to prevent data breaches and unauthorized access, particularly when dealing with proprietary or confidential information. The balance between leveraging data for model improvement and safeguarding individual privacy is a continuous challenge.
Accountability and Transparency
As NLP systems become more autonomous and influential in decision-making processes, questions of accountability become increasingly complex. Who is responsible when an AI system makes an error, perpetuates bias, or causes harm? Establishing clear frameworks for accountability, both for the developers and deployers of AI, is essential. Related to this is the need for transparency. While the inner workings of deep learning models can be opaque (“black boxes”), efforts in Explainable AI (XAI) are crucial for providing insights into how these models arrive at their conclusions. This transparency is vital for auditing, validating, and building trust in NLP systems, especially in high-stakes applications. Without clear accountability and a degree of transparency, the adoption and societal acceptance of advanced NLP technologies could be hindered.
Frequently Asked Questions
What is Natural Language Processing (NLP)?
Natural Language Processing (NLP) is a branch of artificial intelligence that focuses on the interaction between computers and humans using natural language. It involves the processing and analysis of human language data to enable machines to understand, interpret, and generate human language.
How is Natural Language Processing used in real-world applications?
Natural Language Processing is used in various real-world applications such as chatbots, virtual assistants, sentiment analysis, language translation, speech recognition, and text summarization. It is also utilized in spam detection, search engines, and information extraction from unstructured data.
What are some common techniques used in Natural Language Processing?
Some common techniques used in Natural Language Processing include tokenization, part-of-speech tagging, named entity recognition, syntactic parsing, sentiment analysis, machine translation, and text generation. These techniques help in processing and analyzing human language data effectively.
What are the challenges faced in Natural Language Processing?
Challenges in Natural Language Processing include ambiguity in language, understanding context, handling different languages and dialects, dealing with sarcasm and irony, as well as privacy and ethical concerns related to the use of language data. Developing accurate models that can understand and generate human language remains a significant challenge.
How can one get started with learning Natural Language Processing?
To get started with learning Natural Language Processing, one can begin by studying the basics of linguistics, machine learning, and programming languages such as Python. There are various online courses, tutorials, and resources available that cover the fundamentals of NLP, including libraries like NLTK, spaCy, and TensorFlow for practical implementation.
Ready to Scale Your Technical Operations?
Ready to integrate advanced NLP into your workflows? Explore our custom AI Chatbots & Agents services to automate and scale.