· Goher K · AI & Tech · 19 min read
AI Agents vs Chatbots: Key Differences & Enterprise Uses for 2027
Understand the key architectural differences between AI agents and chatbots. Discover autonomous workflows, conversational memory, and practical deployments.
Beyond Basic Bots: From Reactive Chatbots to Proactive AI Agents
For many organizations, the initial foray into AI-driven customer interaction or internal process automation began with rule-based chatbots. These systems, while effective for highly structured inquiries and predefined workflows, invariably hit a ceiling. Their deterministic nature, reliance on rigid ‘if-then’ logic, and inability to handle ambiguity or multi-step reasoning quickly expose their limitations in dynamic business environments. A customer asking a question slightly outside the pre-programmed script, or a request requiring data synthesis from multiple disparate systems, often results in a “I don’t understand” response, a frustrating loop, or an escalation to human intervention. This reactive, single-turn interaction paradigm fails to capture the true potential of AI.
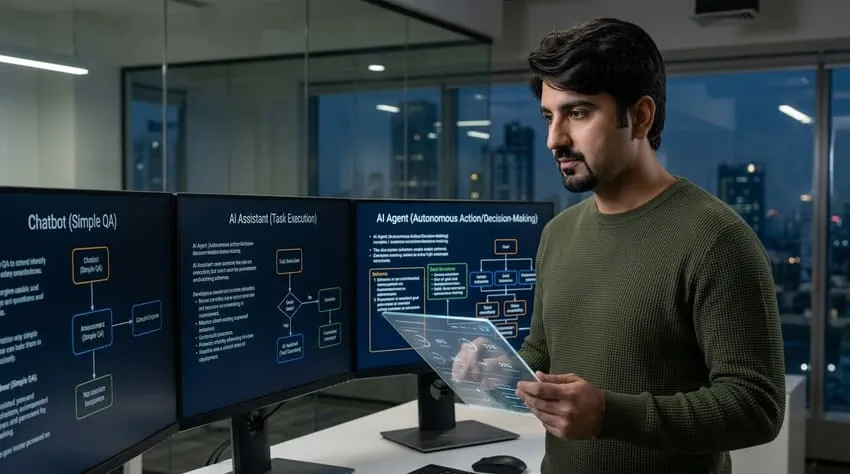
The paradigm shift now occurring is from systems that merely answer to systems that act. This is the fundamental distinction between traditional chatbots and modern AI agents. While chatbots primarily respond to prompts with text, AI agents possess the capability to interpret high-level goals, plan multi-step workflows, choose and execute tools, observe the results of their actions, and update their plans dynamically based on feedback. This inherent autonomy allows them to execute multi-step business logic that is far beyond the scope of any rule-based system or even a basic LLM wrapper. Imagine an agent that doesn’t just tell a customer their order status but can also initiate a return, schedule a pickup, and apply a refund to their account, all while communicating with the customer proactively. This level of proactive, goal-oriented execution is what defines an AI agent and represents a significant leap in enterprise automation. The industry is witnessing a key shift from systems that answer to systems that act, with agents able to interpret goals, choose tools, observe results, and update plans, marking a significant evolution in AI capabilities.
The Limitations of Rule-Based Systems
Rule-based chatbots are essentially decision trees. They excel at closed-domain questions where the answer can be directly derived from pre-programmed conditions. For instance, “What are your business hours?” or “How do I reset my password?” are ideal use cases. However, their deterministic nature becomes a bottleneck when faced with:
- Ambiguity and Nuance: Human language is inherently complex and often ambiguous. Rule-based systems struggle to interpret intent when phrasing deviates even slightly from expected patterns.
- Contextual Understanding: They lack the ability to maintain conversational context over multiple turns or to infer unstated information, leading to repetitive questioning or irrelevant responses.
- Dynamic Information: Any change in business processes, product offerings, or policy requires manual updates to the rule base, making them difficult to scale and maintain in agile environments.
- Multi-Step Problem Solving: Complex customer journeys or internal tasks often require a sequence of actions, data lookups, and conditional logic that cannot be encapsulated in simple rules.
Autonomous Agents: Executing Complex Business Logic
In contrast, autonomous AI agents are designed to handle exactly these challenges. Their architecture typically incorporates a large language model (LLM) as the reasoning engine, coupled with various tools and access to external data sources. This allows them to:
- Understand High-Level Goals: Instead of just keywords, agents interpret the user’s ultimate objective, even if it’s implicitly stated.
- Decompose Complex Tasks: They can break down a broad goal into a series of smaller, manageable sub-tasks.
- Select and Utilize Tools: Based on the sub-tasks, agents can dynamically choose and invoke appropriate internal APIs, external services (e.g., CRM, ERP, payment gateways), or web scraping capabilities.
- Reason and Plan: The LLM’s inherent reasoning abilities allow the agent to formulate a plan of action, execute steps sequentially or in parallel, and adjust its strategy based on intermediate results.
- Observe and Adapt: After executing a tool, the agent observes the output and uses this feedback to inform its next steps, correct errors, or refine its approach, mimicking human problem-solving.
For example, a customer service agent might receive a goal like “I need to change the delivery address for my recent order and confirm the new delivery date.” A traditional chatbot would likely ask for the order number, then provide a static link to a change form. An autonomous agent, however, would:
- Identify the need to locate the order (using a CRM tool).
- Retrieve order details and current delivery address.
- Prompt the user for the new address.
- Call an internal logistics API to attempt an address change.
- If successful, confirm the change and new delivery date.
- If unsuccessful, identify reasons (e.g., package already shipped) and offer alternatives (e.g., redirect to nearest depot, contact carrier directly).
This ability to plan, act, observe, and adapt makes AI agents profoundly more capable and valuable in sophisticated enterprise use cases.
Production AI Architecture: Building Robust Agent Systems
Deploying AI agents in a production environment demands a robust and meticulously engineered architecture that addresses concerns around security, data integrity, latency, and reliability. This is far beyond simply calling an LLM API; it involves orchestrating a complex interplay of components designed for enterprise-grade performance and compliance.
Secure Context Retrieval (RAG Pipelines)
At the heart of many sophisticated AI agent systems is the Retrieval Augmented Generation (RAG) pipeline. While LLMs possess vast general knowledge, they lack specific, up-to-the-minute information about an organization’s internal processes, customer data, product catalogs, or proprietary documentation. This is where RAG becomes critical.
A secure RAG pipeline involves:
- Data Ingestion and Chunking: Enterprise data from various sources (CRM, ERP, internal knowledge bases, documentation, support tickets, product specifications) is ingested, cleaned, and broken down into smaller, semantically meaningful ‘chunks’.
- Vector Embeddings: Each chunk is then converted into a high-dimensional numerical representation (a vector embedding) using an embedding model. These embeddings capture the semantic meaning of the text.
- Vector Databases: These vector embeddings are stored in specialized vector databases (e.g., Pinecone, Weaviate, Milvus). These databases are optimized for rapid similarity searches, allowing the system to quickly find relevant information based on the semantic meaning of a query.
- Secure Retrieval: When an agent receives a query, the query itself is embedded. This query embedding is then used to perform a similarity search in the vector database to retrieve the most relevant data chunks. Importantly, access control mechanisms must be implemented to ensure that agents only retrieve information they are authorized to access, preventing data leaks or unauthorized exposure of sensitive data. For instance, customer service agents should only retrieve data for their assigned customers, and internal HR agents should only access HR policies.
- Context Augmentation: The retrieved context is then dynamically prepended or inserted into the LLM’s prompt, providing the model with the specific, factual information it needs to generate accurate and relevant responses or to inform its next action. This dramatically reduces hallucination by grounding the LLM in verifiable enterprise data.
This secure context retrieval mechanism is paramount for building AI agents that provide factual, consistent, and organizationally compliant responses, moving beyond mere conversational fluency to deliver actionable intelligence.
Function Calling and Tool Execution
The ability of an AI agent to act is predicated on its capacity for function calling and tool execution. This is where the agent moves from being a conversational interface to an operational system.
- Function Definitions: Developers expose internal APIs, microservices, or external third-party services as ‘tools’ or ‘functions’ to the LLM. Each function has a clear schema defining its purpose, required parameters, and expected output. For example, a
getCustomerOrderHistory(customer_id)function might be exposed. - LLM Reasoning for Tool Use: When presented with a goal, the LLM analyzes the request and determines if any available tools can help achieve that goal. It then generates the precise function call, including all necessary parameters, based on its understanding of the user’s intent and the tool’s schema.
- Tool Execution and Observation: The generated function call is executed by an orchestration layer. The output of the tool (e.g., a customer’s order history) is then fed back to the LLM as additional context. The LLM observes this output and decides on the next step: whether to call another tool, synthesize a response, or ask for clarification.
- Multi-Agent Orchestration: For highly complex business processes, multiple specialized agents might need to collaborate. One agent might handle customer interaction, another might manage inventory, and a third might handle payment processing. A central orchestrator would manage the communication and task hand-off between these agents, ensuring a seamless workflow. This multi-agent orchestration mimics real-world team collaboration, where different specialists contribute to a common objective.
This robust function calling mechanism is what transforms an LLM into an operational agent capable of interacting with and manipulating external systems.
Fallback Routines and Human-in-the-Loop
Even the most advanced AI agents are not infallible. Hallucinations, ambiguities, or requests requiring empathy or nuanced judgment can arise. Production-grade AI architectures must incorporate robust fallback routines and a human-in-the-loop mechanism to ensure graceful degradation and maintain service quality.
- Confidence Scoring: Agents can be designed to assess their own confidence level in understanding a query or executing a task. If confidence drops below a predefined threshold, a fallback routine is triggered.
- Escalation to Human Agents: The most common fallback is seamless escalation to a human agent. This requires passing the full conversational context, retrieved information, and the agent’s attempted actions to the human, enabling them to pick up the conversation or task without the user having to repeat themselves.
- Clarification Prompts: For minor ambiguities, the agent can be programmed to ask clarifying questions rather than immediately escalating.
- Pre-defined Responses: For certain critical queries or unrecognized intents, a pre-defined, safe fallback response can be provided, perhaps directing the user to a specific support page or phone number.
- Monitoring and Alerting: Real-time monitoring of agent performance, error rates, and unresolved queries is essential. Alerts should be triggered for anomalies, allowing operations teams to intervene proactively.
This layered approach to error handling ensures that even when the AI agent cannot fully resolve a situation, the user experience remains positive, and critical tasks are not dropped.
Low-Latency Responses
In enterprise applications, particularly customer-facing ones, low-latency responses are critical for a positive user experience. Users expect near-instantaneous replies, and any significant delay can lead to frustration and abandonment.
- Optimized Model Inference: Choosing the right LLM model is crucial. Smaller, more specialized models can offer faster inference times for specific tasks. On-premises or hybrid deployments with dedicated GPU infrastructure can also reduce latency compared to public cloud APIs, though this comes with higher infrastructure costs.
- Caching Mechanisms: Caching frequently requested data or pre-computed responses can significantly reduce the need for repeated API calls or complex retrieval operations.
- Asynchronous Processing: For multi-step agent actions, where some steps might involve external API calls with inherent latency, asynchronous processing can be employed to manage concurrent operations and avoid blocking the main thread.
- Efficient Prompt Engineering: Well-designed prompts that are concise and clear reduce the computational load on the LLM and lead to faster generation.
- Network Optimization: Minimizing network hops and ensuring low-latency connectivity to LLM providers and internal services are fundamental.
Achieving low-latency responses in complex AI agent systems requires a holistic approach that considers model choice, infrastructure, caching strategies, and efficient system design. This technical focus ensures that autonomous agents not only perform complex tasks but do so with the speed and responsiveness expected in modern business operations.
In-House Integration Friction: Navigating the Challenges
Building and integrating production-grade AI agents internally presents a unique set of challenges that extend beyond purely technical implementation. Organizations often grapple with issues like mitigating hallucinations, managing escalating token costs, and navigating API rate limits, all while ensuring data privacy and security. These are not trivial concerns and require strategic planning and robust operational procedures.
Hallucination Mitigation Strategies
Hallucinations, where LLMs generate factually incorrect or nonsensical information, remain a significant concern, especially in enterprise contexts where accuracy and reliability are paramount. While RAG pipelines significantly reduce this risk by grounding the LLM in factual data, complete elimination is challenging.
- Enhanced RAG and Grounding: Beyond basic RAG, implementing advanced grounding techniques such as re-ranking retrieved documents, incorporating knowledge graphs, or cross-referencing information from multiple authoritative sources can further reduce hallucinations.
- Fact-Checking Modules: For critical applications, integrating a separate fact-checking module that uses external APIs or internal databases to verify the LLM’s generated statements can add an extra layer of defense.
- Confidence Scores and Uncertainty Handling: As mentioned previously, agents can be designed to express uncertainty or to escalate to a human when their confidence in a generated response is low.
- Strict Prompt Engineering: Crafting highly specific and restrictive prompts that guide the LLM’s output and explicitly instruct it to state when it doesn’t know the answer can limit creative but incorrect outputs.
- User Feedback Loops: Implementing mechanisms for users to flag incorrect or unhelpful responses provides valuable data for continuous model refinement and identifies areas where hallucinations are more prevalent. This human feedback is crucial for iterative improvement.
Managing Token Costs
LLM API calls are typically billed based on the number of ‘tokens’ processed, which includes both the input prompt and the generated output. As agent systems scale and handle more complex, multi-turn interactions or large context windows, token costs can quickly become a significant operational expense.
- Context Window Optimization: While larger context windows allow for more comprehensive reasoning, they also consume more tokens. Strategies include:
- Summarization: Summarizing long internal documents or conversational history before feeding them into the LLM.
- Selective Context Retrieval: Only retrieving and including the most immediately relevant information from the RAG pipeline.
- Sliding Context Windows: Dynamically adjusting the context window to focus on the most recent and relevant parts of the conversation.
- Model Selection: Utilizing smaller, more efficient LLMs for less complex tasks, reserving larger, more expensive models for tasks requiring sophisticated reasoning. Many providers offer tiered models with different cost-performance trade-offs.
- Caching of Common Responses: For frequently asked questions or recurring tasks, caching the generated responses can eliminate the need for repeated LLM calls.
- Prompt Compression Techniques: Experimenting with techniques to condense prompts without losing meaning, thereby reducing the input token count.
- Batching API Calls: Where possible, batching multiple requests into a single API call can sometimes offer cost efficiencies, though this depends on the specific LLM provider’s API.
Proactive cost monitoring and optimization are essential to ensure the financial viability of large-scale AI agent deployments.
Navigating API Rate Limits
LLM providers impose rate limits on API calls to manage server load and ensure fair usage. For high-volume enterprise applications, these limits can become a bottleneck, leading to throttled requests, increased latency, and degraded user experience.
- Distributed Architectures: Spreading API requests across multiple API keys or accounts (where permissible and practical) or using different regions/endpoints can help distribute the load.
- Intelligent Queuing and Retries: Implementing robust queuing mechanisms to manage outbound API requests and incorporating exponential backoff and retry logic for throttled requests.
- Load Balancing and Concurrency Control: Designing the agent system to intelligently manage concurrent API calls and distribute them across available resources.
- Prioritization: Prioritizing critical agent tasks over less urgent ones when hitting rate limits.
- Proactive Rate Limit Monitoring: Integrating API rate limit headers into monitoring systems to receive alerts when nearing limits, allowing for proactive adjustments or scaling.
- Negotiating Higher Limits: For large enterprise deployments, it’s often possible to negotiate higher rate limits directly with LLM providers based on anticipated usage and financial commitment.
Successfully integrating AI agents within an existing enterprise ecosystem requires a deep understanding of these operational challenges and the implementation of sophisticated solutions to address them. The complexities involved underscore the need for specialized expertise in designing and managing these advanced AI systems.
Discover the future of customer service with our innovative AI Chatbots & AI Agents. These intelligent systems are designed to enhance user interaction and streamline processes. Explore how AI Chatbots & AI Agents can transform your business operations today.
Seamless Pivot & Strategic Partnership for AI Agent Implementation
The transition from conceptualizing AI agents to implementing them as production-ready, mission-critical systems is a significant undertaking. The challenges discussed – from robust RAG pipelines and tool orchestration to hallucination mitigation, cost management, and API rate limit navigation – demand a level of expertise and experience that often extends beyond an organization’s core competencies. While major product launches like OpenAI’s proposed consumer-facing agent ‘Aeon’ and Meta’s ‘Muse’ are accelerating the trend, and new real-world uses in household assistance, shopping, and customer service are expanding, the adoption is still uneven, with concerns about unauthorized actions and security bypasses pushing companies towards stronger controls and human oversight.
Attempting to build and integrate these complex AI systems entirely in-house without prior experience can lead to costly delays, technical debt, and suboptimal performance. This is where strategic partnerships become invaluable.
Navigating the complexities of custom AI agent development, from initial strategy and architecture design to secure deployment and ongoing optimization, requires a deep understanding of both AI technologies and enterprise operational realities. Specialized partners bring proven methodologies, architectural blueprints, and engineering talent experienced in addressing the unique challenges of large-scale AI deployments. This includes expertise in designing multi-agent orchestration frameworks, implementing sophisticated LLM API routing for efficiency and reliability, and ensuring seamless integration with existing CRM/ERP systems to unlock the full potential of autonomous automation.
Consider the potential for increased scam, fraud, privacy, and security risks warned by banks and media reports, especially when AI shopping agents handle payments or interact with external sites. A vetted implementation partner can provide the necessary governance, security frameworks, and human oversight mechanisms to mitigate these fresh risk concerns, building trust in your AI initiatives. They also bring an understanding of performance and cost implications, informed by recent field experiments showing faster handling for some agent-assisted chats, while also acknowledging that agents can use far more electricity and take much longer per complex request than chatbots. This balanced perspective ensures that solutions are not only powerful but also economically viable and environmentally responsible.
At igoher.com, we specialize in transforming ambitious AI concepts into tangible, high-performing enterprise solutions. Our focus is on strategic, zero-fluff implementation that delivers measurable business value. We guide CTOs, product heads, and ops leaders through the entire lifecycle of AI agent deployment, ensuring that your investment translates into truly autonomous capabilities.
Our approach addresses the full spectrum of challenges:
- Architecture & Design: Crafting scalable, secure, and resilient AI agent architectures tailored to your specific business processes and data landscape.
- Secure Integration: Deep expertise in integrating AI agents with your existing CRM, ERP, and other critical business systems, ensuring data integrity and seamless workflows. We build robust RAG pipelines for secure context retrieval, ensuring your agents operate on accurate, authorized data.
- Performance Optimization: Engineering for low-latency responses, efficient token management, and intelligent LLM API routing to optimize performance and control costs.
- Risk Mitigation: Implementing advanced strategies for hallucination mitigation, robust fallback routines, and human-in-the-loop mechanisms to ensure reliability and compliance.
- Multi-Agent Orchestration: Designing and deploying complex multi-agent systems that coordinate diverse functions and achieve sophisticated, multi-step business objectives.
Don’t let the promise of AI agents remain a theoretical aspiration. Partner with experts who understand the nuances of production-grade AI systems and can navigate the inherent complexities.
Ready to elevate your enterprise capabilities with production-grade AI agents?
Let’s discuss how igoher.com/services/ai-agents/ can help you transition from basic chatbots to truly autonomous AI. Our custom AI agent development expertise ensures that your AI initiatives are strategic, secure, and impactful. For a deeper dive into how we build and deploy enterprise-grade AI agents, visit igoher.com/services/ai-agents/.
Schedule a discovery call today to explore how our specialized capabilities can accelerate your AI journey and deliver tangible business outcomes.
Frequently Asked Questions
What is the difference between AI agents and chatbots?
AI agents are more advanced than chatbots as they can understand context, learn from interactions, and make decisions. Chatbots, on the other hand, are rule-based and provide pre-programmed responses based on keywords.
How do AI agents improve customer service compared to chatbots?
AI agents can provide more personalized and efficient customer service by analyzing data, understanding natural language, and adapting to user behavior. Chatbots, while useful for basic queries, lack the ability to handle complex interactions.
Can AI agents be integrated with chatbots for better performance?
Yes, AI agents can be integrated with chatbots to enhance their capabilities. By combining the strengths of both technologies, businesses can offer a more comprehensive and effective customer service experience.
What are some industries that can benefit from using AI agents over chatbots?
Industries such as healthcare, finance, and e-commerce can benefit greatly from using AI agents due to their ability to handle sensitive data, provide personalized recommendations, and offer more sophisticated solutions to customer queries.
Are there any limitations to using AI agents instead of chatbots?
While AI agents offer more advanced capabilities, they can be more expensive to develop and maintain compared to chatbots. Additionally, AI agents may require more training data and expertise to ensure optimal performance.
Ready to Scale Your Technical Operations?
Upgrade from scripted bots to intelligent automation. Let’s build custom AI Agents tailored for your enterprise.